Platform Standardization Decisions for Protein Expression in R&D Labs
Labs must weigh cell-based and cell-free systems against protein needs, throughput, reproducibility.
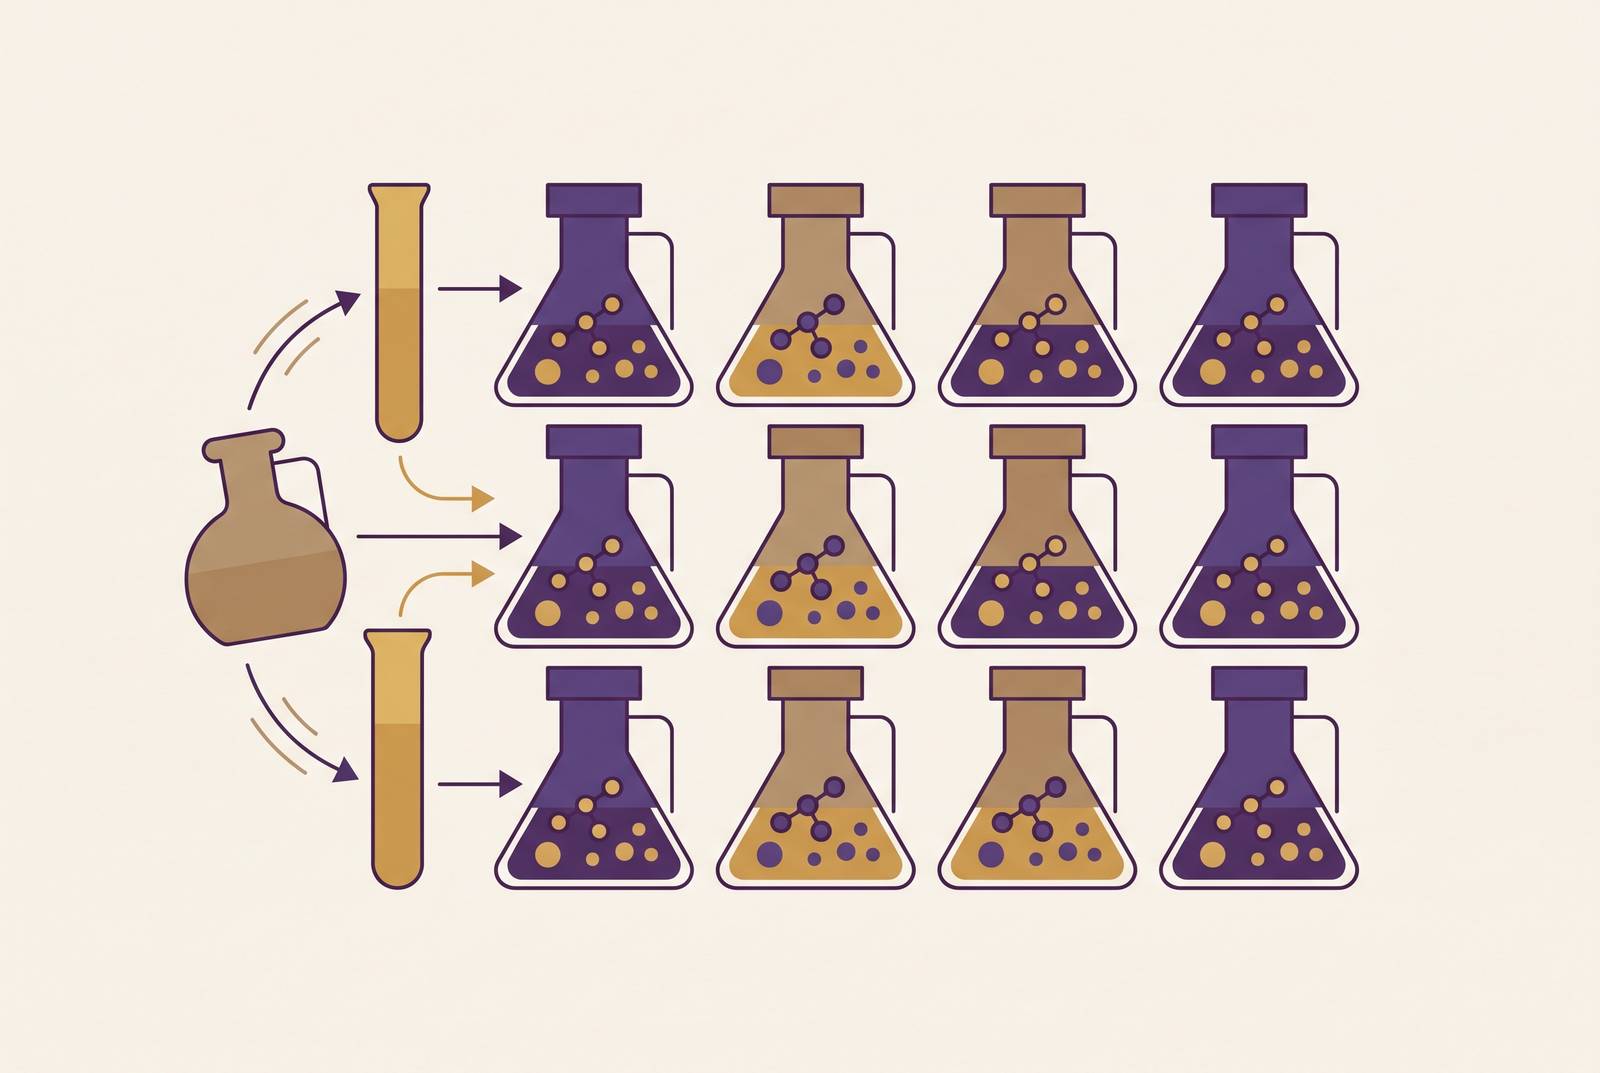
Protein expression platform standardization is a decision about fit. R&D labs need to weigh cell-free and cell-based approaches against four axes, namely protein target properties, throughput, reproducibility, and workflow integration. The right outcome is a platform, or a bounded set of platforms, that meets those requirements at the scale the lab actually uses.
Why labs standardize protein expression platforms rather than running each project on its own terms
Project-by-project expression choices accumulate costs beyond the individual experiment. Different reagent inventories support incompatible protocols, while inconsistent QC baselines make results harder to compare across experiments and time. Each project may work well on its own. But the lab may struggle to give those projects a shared way of working that produces reproducible results.
Standardization means selecting against defined criteria and holding to that selection so that workflows, reagent lots, and results remain comparable. This choice becomes especially consequential when a lab is being built or scaled, or when it takes on a protein class that its current platform handles poorly. A rational decision therefore begins by applying the four-axis framework to the system already on the bench.
The two main architectures a lab must choose between and what each one actually is
Cell-based expression uses living cells to make proteins. Its major chassis options include E. coli, yeast, insect cells, and CHO/HEK293 cells, with different post-translational modification capacity and cost profiles. Cell-free protein synthesis, or CFPS, instead uses synthetic machinery taken from cells in an open reaction vessel.
Within CFPS, crude cell-extract systems retain the full complement of cellular machinery from sources including E. coli, wheat germ, insect cells, and mammalian cells. They offer higher yields and lower cost than reconstituted systems, but retain some background activity from endogenous enzymes. PURE systems take the other route. Each component is individually purified and assembled, giving a defined composition with near-zero nuclease and protease activity. They give much lower yields and cost more in reagents, but knowing exactly what is in the reaction makes them well suited to mechanistic studies and degradation-sensitive proteins. These descriptions establish the alternatives, but do not select among them without the target and operating requirements.
How protein target properties determine which platform can actually do the job
The protein itself is the first filter. A platform that cannot express it correctly is not a candidate, regardless of convenience or cost. For well-behaved soluble proteins without special modification needs, cell-based expression works reliably. That is a valid basis for a narrow portfolio, but it becomes insufficient when the target set expands to include proteins with more demanding requirements.
Authentic mammalian glycosylation, including full Golgi processing, remains an advantage of CHO and HEK293 cells because no cell-free system fully replicates that pathway. Prokaryotic cell-based systems also fall short, frequently producing modification patterns that diverge from the native protein. Eukaryotic hosts therefore remain necessary for some targets despite their cost. The relevant comparison is not simply cells against extracts, but the required modification against the capacity of the specific system.
Other target requirements favor access to the reaction. CFPS supports disulfide bond formation through oxidizing conditions, cofactor-dependent folding through added cofactors, and non-standard amino acid incorporation through orthogonal tRNA/synthetase pairs. Cell-based systems need host engineering to do the same things. Where a portfolio includes toxic, membrane-bound, or modification-sensitive targets that cell-based systems cannot handle reliably, CFPS belongs in the platform set, although the mammalian glycosylation constraint still applies.
How throughput requirements shift the calculation
At high variant counts, cell-based systems become a structural bottleneck because each variant requires cloning, transformation, colony selection, and culture. A host may express every target well enough and still take too much work to use across the library. Throughput is therefore an independent decision axis.
At medium throughput, spanning tens to low hundreds of variants, microplate CFPS is already practical. Its relevance grows when the target list turns over quickly, as in active lead optimization. A changing library creates a different workload from repeated expression of an established protein. The inflection point consequently depends on turnover as well as variant count.
A lab repeatedly expressing a handful of well-defined proteins at production scale can amortize cell-based fermentation setup over many runs. In that setting, the ability of CFPS to express proteins in parallel is less of a benefit. Late-stage characterization generally sits nearer the low-throughput end than active lead optimization. The selection process should therefore assess the expected workload explicitly rather than assume that the current target list represents the lab’s future needs.
Why reproducibility and reagent transparency are non-negotiable standardization requirements, not vendor preferences
A platform that performs well but cannot be controlled across batches is not a sound standardization foundation. CFPS has historically faced extract-to-extract differences, DNA template variability, and batch inconsistencies, compounded by a lack of validated extract standards and transparent formulations. Results from cell-based systems can vary too, because of media lots, host strain drift, and plasmid stability. Opaque formulations make relevant changes harder to diagnose in either architecture.
A Shandong University preprint (2025) reduced the essential core reaction components of an E. coli CFPS system from 35 to 7 through systematic screening while maintaining or improving protein expression. Fewer components simplify documentation, verification, and reproduction of the formulation. This is evidence that complexity can be reduced. In separate work, liquid-handling platforms have shown little batch-to-batch variability over repeated CFPS experiments when the same protocols are followed each time.
Lot-level QC gives the lab the data it needs to spot drift. Data showing what each batch actually produced are more useful for that purpose than a statement that it passed a threshold. Documented, open formulations also let scientists check each component when results change, so they can do more of that work without help from the supplier. OpenCFPS™ provides published formulations and lot-level QC data as standard. Its relevance to standardization follows from those provisions, because they give the lab an information base for comparing batches and troubleshooting independently.
How workflow integration requirements constrain platform choice in practice
Reagent control is necessary, but deployment also depends on infrastructure. Dedicated equipment, specialized incubation conditions, or non-standard plate formats can block adoption when a lab’s infrastructure is already committed. Integration cost belongs in the platform decision because a technically capable system may still be impractical for the team expected to operate it.
CFPS reactions can run on standard automated liquid-handling platforms, including pipetting robots. The automation used for compound dispensing can also run cell-free reactions, with less work by hand and more consistent results. Cell-based expression has a different infrastructure footprint. It requires culture vessels, centrifuges, and induction protocols, with humidity- and CO₂-calibrated incubators for mammalian systems. Large labs often have this equipment, but it can be a substantial obstacle for smaller teams or groups adding a new protein class.
For high-throughput screening, plate compatibility connects expression directly to the downstream assay. CFPS can produce protein and support the assay in the same well, collapsing two steps into one. That capability makes the assay format part of the expression decision. OpenCFPS™ is designed to work with the plate-based workflows and automation systems a lab already has, without the need for specialized equipment. The practical assessment is whether that fit matches the lab’s plates, automation, and downstream readout, rather than whether automation is available in principle.
Where scale tips the economics toward cell-based systems and where it does not
Above gram-scale production, cell-based fermentation retains a real economic advantage. A standard E. coli fermentation run produces protein at a fraction of the per-milligram cost of conventional CFPS reagents, and that difference has historically been decisive for production-scale work. This is the strongest economic objection to CFPS. It applies directly to gram-to-kilogram commercial manufacturing, where repeated production rewards the cell-based approach.
Research-scale economics do not follow automatically from manufacturing economics. Most R&D labs need micrograms for assay development through milligrams for characterization, below the scale at which cell-based systems become clearly cheaper. Simplified CFPS formulations reduce reagent complexity and preparation demands, with some associated cost savings. The Shandong preprint’s primary emphasis, however, was simplification and improved yield. It supports the direction of improvement without establishing a universal cost advantage.
The CFPS architecture also changes the economic comparison. PURE systems cost more and yield less than crude extracts, but exact composition can be a requirement in mechanistic work. Crude-extract CFPS is increasingly cost-competitive for screening and milligram-scale production, where its throughput advantages can also favor selection. OpenCFPS™ pricing is intended to put milligram-scale CFPS within reach of labs that have defaulted to cell-based expression on cost grounds.
A decision framework that maps the four axes onto a platform recommendation
The practical process begins by defining the protein portfolio and identifying its hard constraints. Does it include toxic, membrane-bound, or modification-sensitive targets that cell-based systems cannot handle reliably? If so, CFPS must be part of the platform set, while authentic mammalian glycosylation remains a reason to retain mammalian cells. Next comes the throughput requirement. CFPS is a better fit for large variant libraries, while cell-based expression is a better fit for making large amounts of a few defined proteins over many runs. The lab should also weigh how often it expects its targets to change.
Reproducibility is the third gate. The selected reagent supply must support lot-level QC and documented formulations so that the lab can compare batches and investigate changes. A system without that information cannot provide the required foundation, even if its expression performance is attractive. Fourth, plates, automation, and incubators must support the chosen workflow without capital investment the lab cannot justify.
Taken together, these questions point to CFPS for most R&D labs that work on protein engineering, enzyme discovery, or variant screening at research scale. Labs that focus on production at gram-plus scale, and labs that need authentic mammalian glycosylation, have good reasons to choose cell-based systems as their main platforms. A hybrid is also a deliberate outcome. CFPS can support screening and early characterization, with cell-based systems used for final production, provided the handoff criteria are defined and held consistent between projects.
Within that hybrid, OpenCFPS™ is designed to provide high-throughput screening and milligram-scale production in one documented, lot-QC’d reagent system. Its intended role is to support that research span without a vendor change or protocol reformulation mid-project. The framework does not depend on choosing it. The lab’s task is to define target constraints, assess throughput, require reagent transparency, and establish infrastructure fit before committing resources, then set explicit handoffs wherever more than one platform is needed.
Sources
- A simplified and highly efficient cell-free protein synthesis system for prokaryotes
- Eukaryotic cell-free protein synthesis: Chassis diversification, system engineering, and emerging applications - ScienceDirect
- Cell-Free PURE System: Evolution and Achievements
- A User’s Guide to Cell-Free Protein Synthesis
- Cell-free protein synthesis as a method to rapidly screen machine learning-directed protease variants